LangChain Chatbot with Ollama and Google Gemma
Overview
This project showcases an interactive chatbot built using LangChain, Ollama, and Google’s Gemma 2B large language model. The application allows users to ask natural language questions and receive AI-generated responses with real-time feedback. It demonstrates practical integration of LLMs using a modular and observable architecture.
Table of Contents
Introduction
The chatbot application uses the gemma:2b model served locally via Ollama and orchestrated using LangChain. The user interface is built in Streamlit, and optional observability is enabled using LangSmith. This project is an example of how lightweight LLMs can be used efficiently in production-ready apps.
System Architecture
Prompt Engineering & LangChain
- A predefined system message and user query template are used for consistent interactions.
- The LangChain framework handles chaining and output parsing.
Ollama LLM Backend
- The Gemma 2B model is served locally through Ollama for low-latency inference.
- This avoids dependency on external APIs for inference.
Streamlit Frontend
- A lightweight Streamlit interface is provided for easy interaction.
- Users can type questions and get answers in real time.
Demo
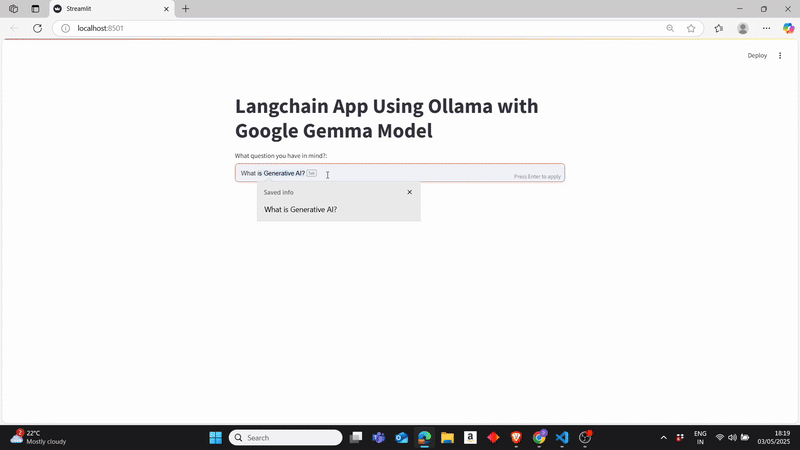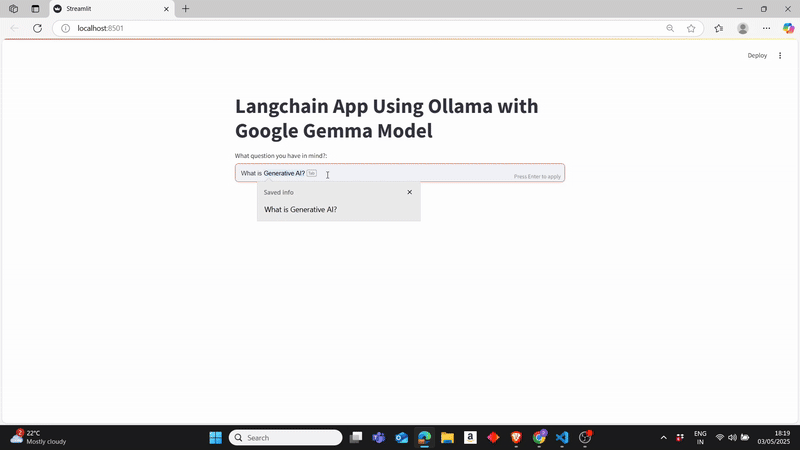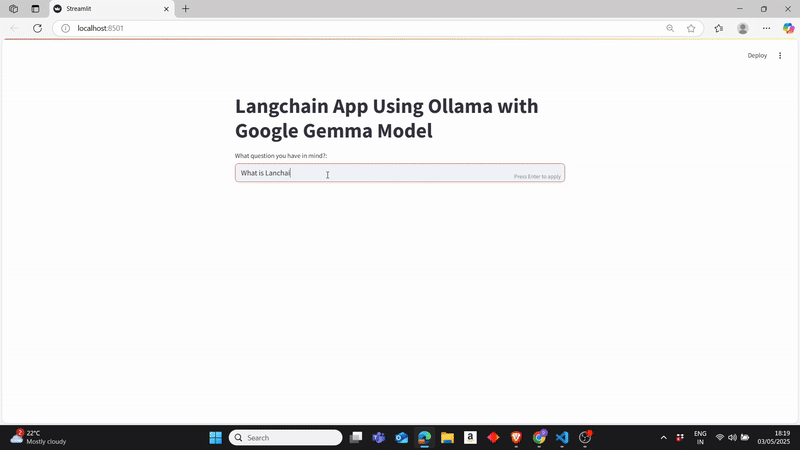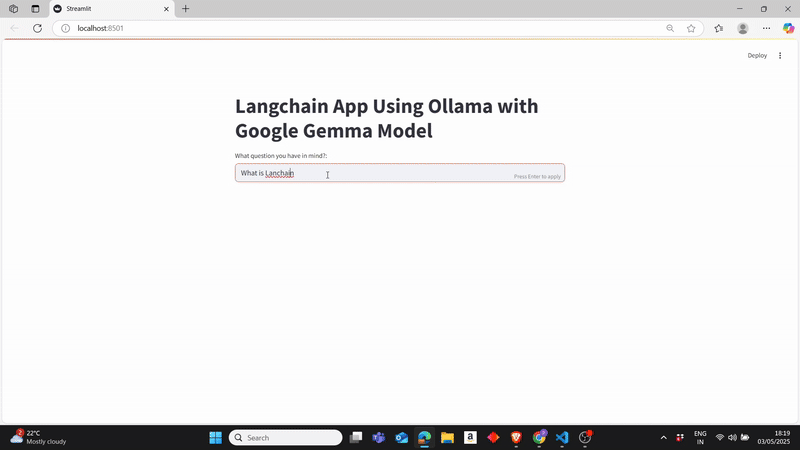
Figure 2: Real-time interaction with the chatbot
Technologies Used
- LangChain – for prompt orchestration and chaining
- Ollama – to serve Gemma 2B LLM locally
- Google Gemma 2B – open-source LLM for inference
- Streamlit – frontend interface
- LangSmith – optional observability for debugging chains
- Python-dotenv – for secure environment configuration
💡 This project highlights the power of local LLMs for real-world use cases and the potential of open-source tools in delivering high-quality AI applications.